PhyML
Overview: new algorithms, methods and utilities
PhyML is a software package that uses modern statistical approaches to build phylogenetic trees from the analysis of alignments of nucleotide or amino acid sequences. The main tool in this package builds phylogenies under the maximum likelihood criterion. It implements a large number of substitution models coupled to efficient options to search the space of phylogenetic tree topologies.
The version that you can try inline on this page is PhyML 3.3. You can get and install it by downloading the code from https://github.com/stephaneguindon/phyml/.
Installation
Get the latest version !
You would find all PhyML releases here : https://github.com/stephaneguindon/phyml/releases
After unpacking the archive, go into the phyml/ folder and type the following command:
sh ./autogen.sh;If you are using a Mac computer or running a Unix-like operating system, you will need to install the packages autoconf automake and pkg-config. On a Mac, the following command should set you up (provided Homebrew is installed on your Mac…): brew install pkg-config autoconf automake;
Next, to install any program that is part of the PhyML package, type the following commands:
./configure --enable-phyml;
make;
To compile a Windows executable, install MinGW and run:
./configure --enable-win --enable-phyml;
make;
To install the MPI version of PhyML, type the following commands:
autoreconf -i;
./configure --enable-phyml-mpi;
make;
PhyML online execution
Other tools
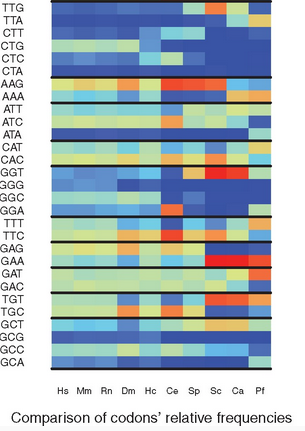
RSCU_RS: Measuring the bias in…
Overview Overview: In the protein coding sequences of a species, the 61 possible codons of the genetic code are not equally distributed. This observation is referred to as the Codon Usage Bias (CUB) of a species. Several measures have been proposed to quantify the CUB using the frequencies of codons in all RNA coding sequences…
AQUAPONY
AquaPony: interactive visualization of phylogeographic scenarios AquaPony is a web application designed to explore and interpret evolutionary scenarios on annotated phylogenetic trees (for example, ancestral geographic states). It was built to make uncertainty in ancestral reconstructions easier to understand and communicate. Why AquaPony? In phylogeography, several scenarios can be nearly as plausible as the best…
LoRDEC: hybrid correction of long…
Overview In a nutshell, LoRDEC is a program for error correcting long sequencing reads using short reads. It implements a hybrid correction approach. It uses little memory and is very efficient. Most importantly it scales up to process very large data sets. It can be applied to long reads obtained with either Pacific Biosciences SMRT…